Agent Readiness Assurance
Scanners check files. We complete the task.
Real AI agents from every vendor, and the people they act for, run your live funnels before every release. alt.qa shows you the exact step where each one fails, with the recording.
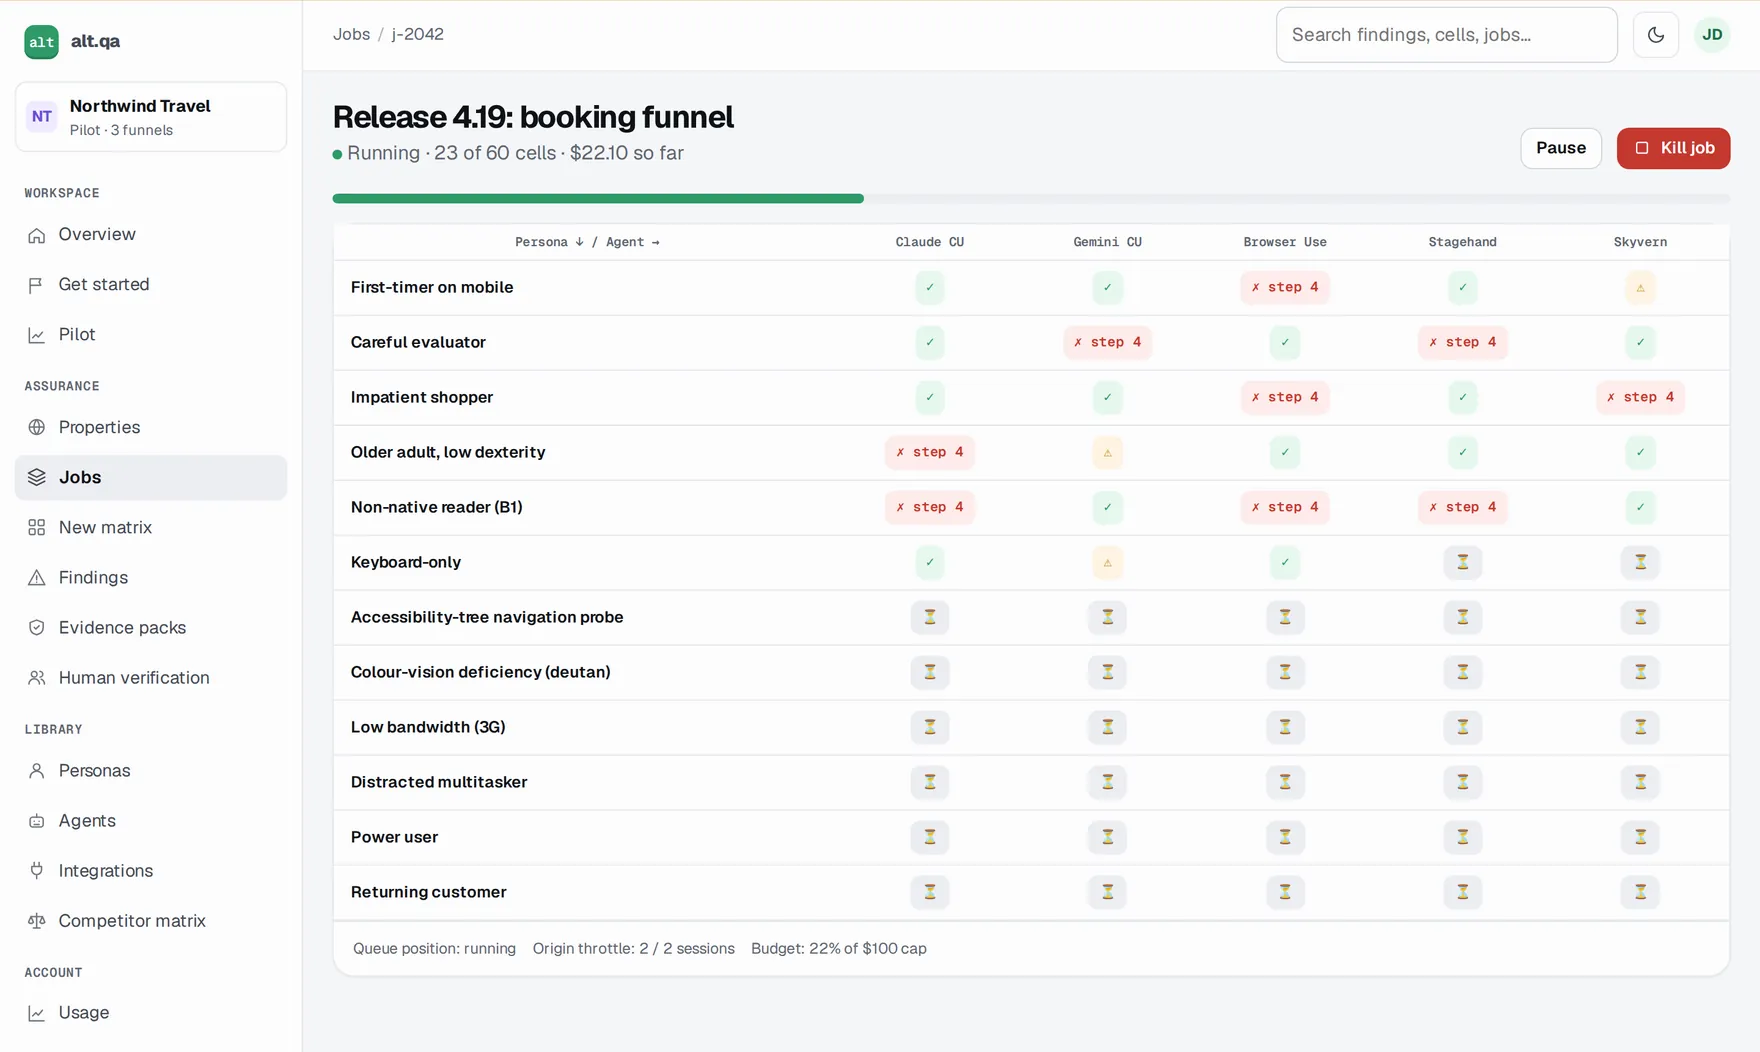
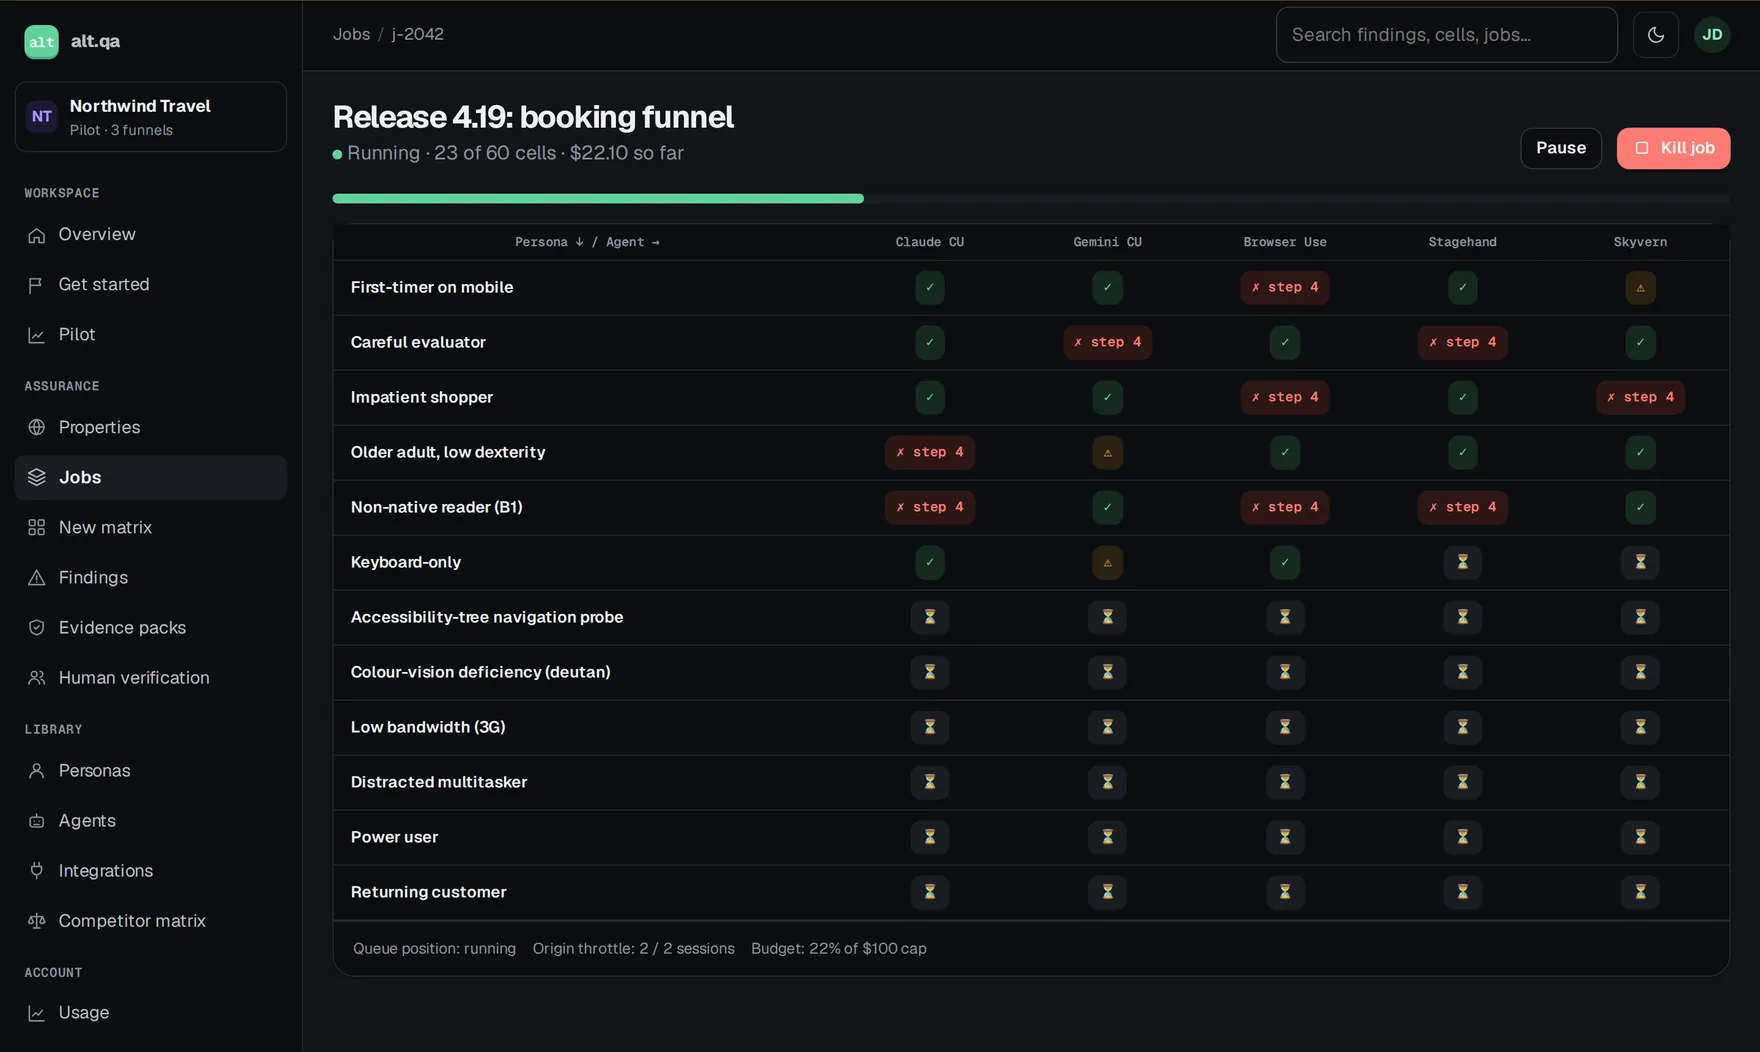
checkout · northwind-travel.exampleSample data
| Persona ↓ / Agent → | Claude CU | Gemini CU | Browser Use | OpenAI CUA |
|---|---|---|---|---|
| First-timer, mobilepatience 5 · iPhone | ||||
| Impatient shopperpatience 2 | ||||
| Older adult, low dexteritymin target 44px | ||||
| Non-native reader (B1)CEFR B1 | ||||
| Keyboard-onlyno pointer |
Column fails → agent-class problemRow fails → persona problemSame step in ≥3 cells → product bug
Click any cell to see the blocking step and evidence.
Agents we run, under alt.qa’s own signed identity
Claude computer useGemini computer useBrowser UseOpenAI CUA Q1Stagehand Q1Skyvern Q1
Your next customer is sometimes an agent.
And when it cannot get through, the sale is gone before your monitoring notices.
+54%
Adobe: AI-referred retail traffic converted 54% better than other traffic (May 2026, US retail).
⅓
Walmart: in-ChatGPT checkout converted at about one-third the rate of click-out to walmart.com.
Source: Search Engine Land, Mar 2026
20%
Salesforce forecasts 20% of holiday-2026 e-commerce traffic will originate from AI chat agents (a forecast of traffic, not orders).
Source: Salesforce, Jul 2026
Nobody tests for that customer before release.
- Readiness scannersCheck files agents mostly ignore. 97% of published llms.txt files never get a single request.Scanners vs assurance →
- MonitoringShows agent friction after the sale is lost. Useful, and too late.Monitoring vs prevention →
- Your QA suiteTests your app as one idealised user of your own design.For QE teams →
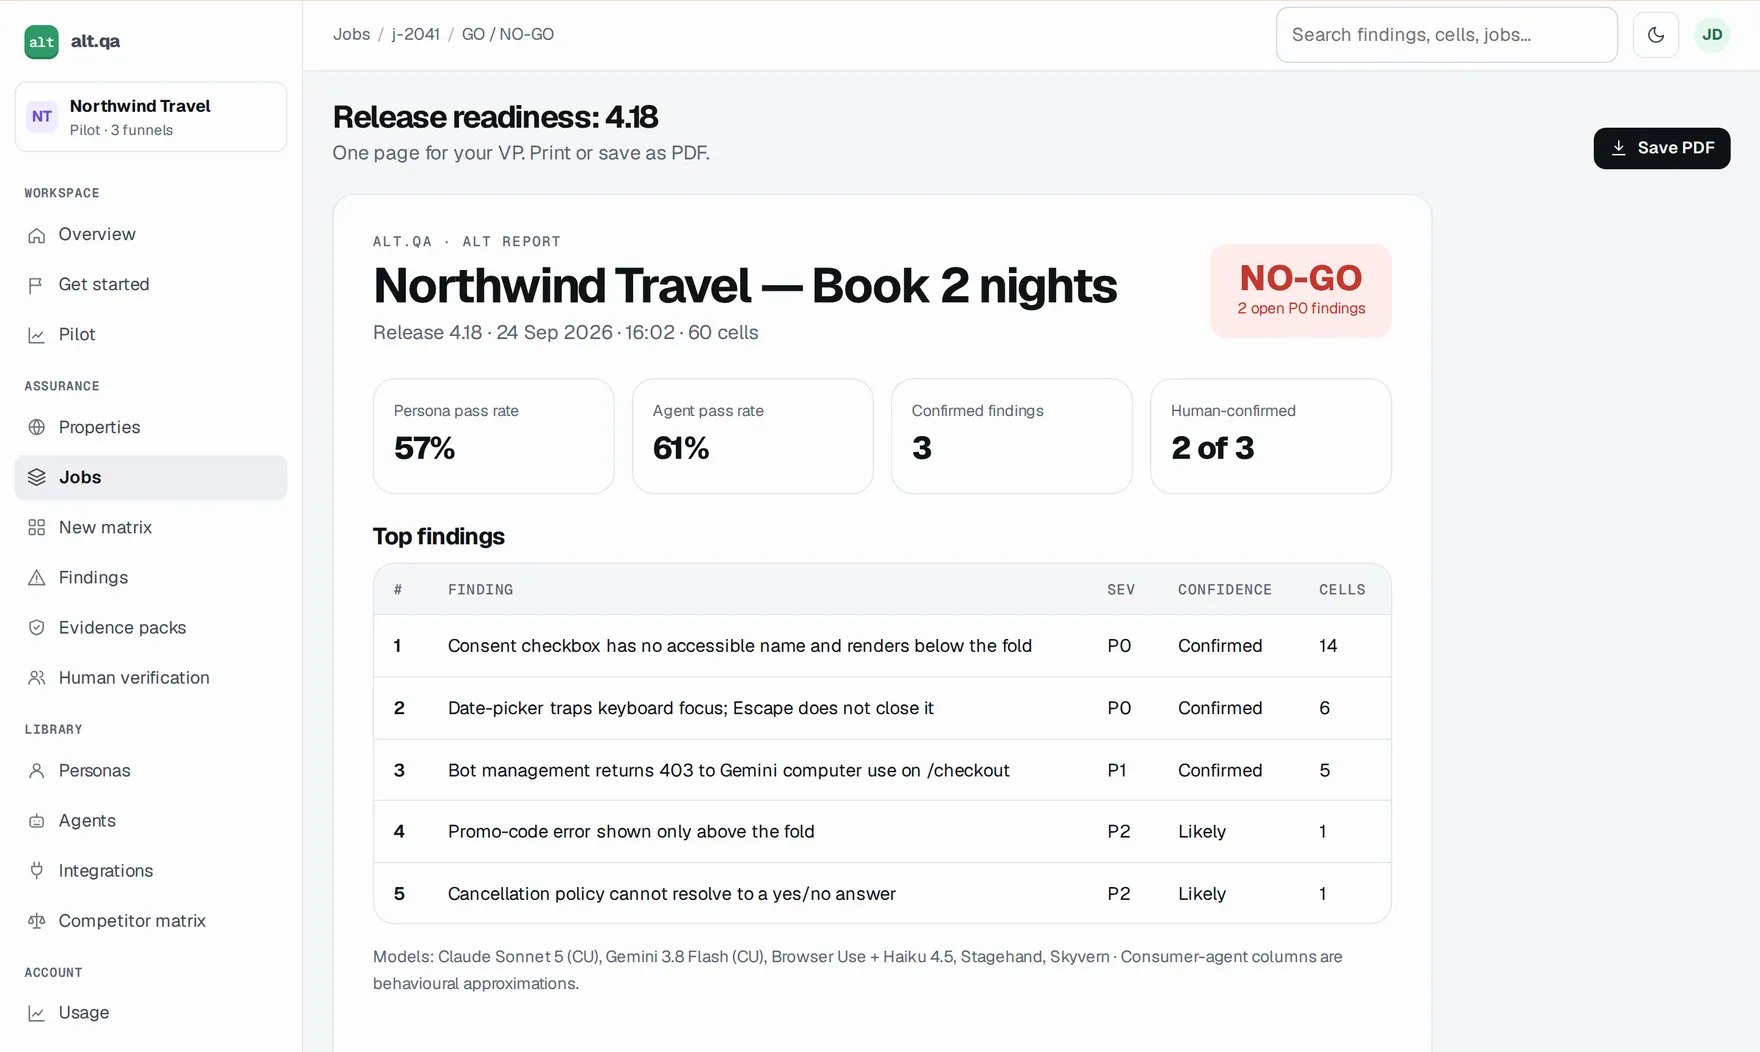
Alt Report
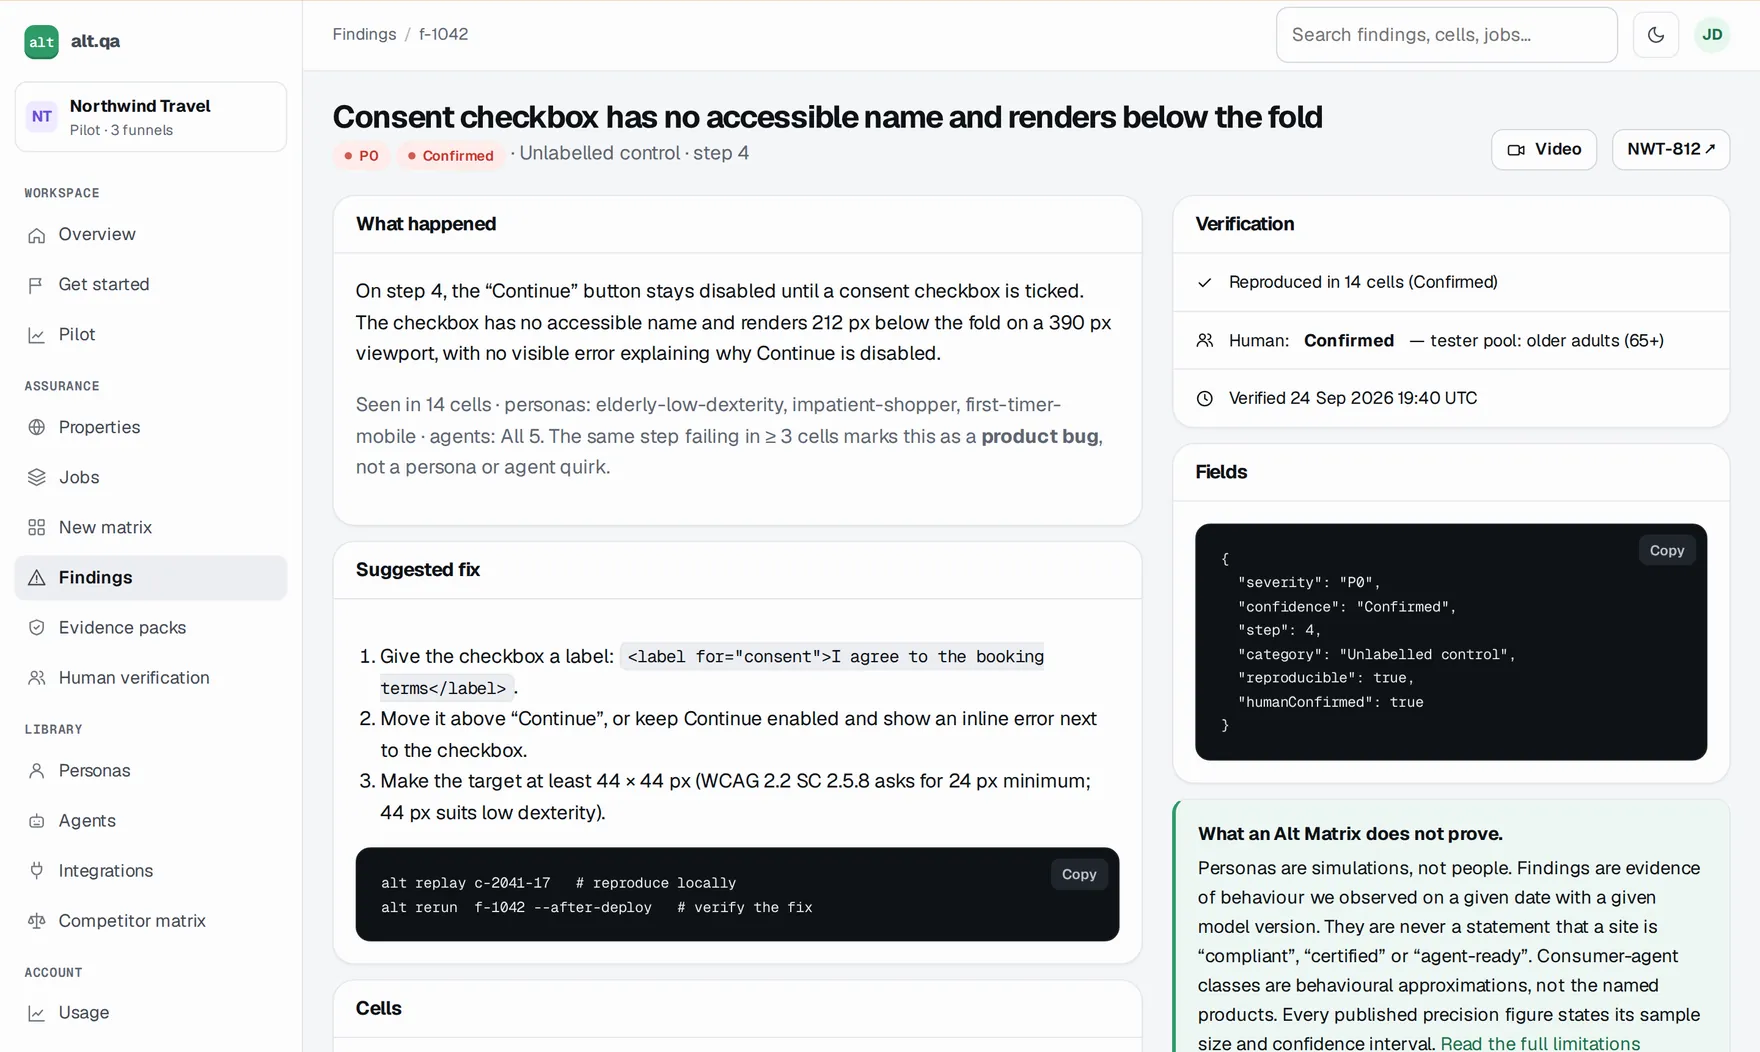
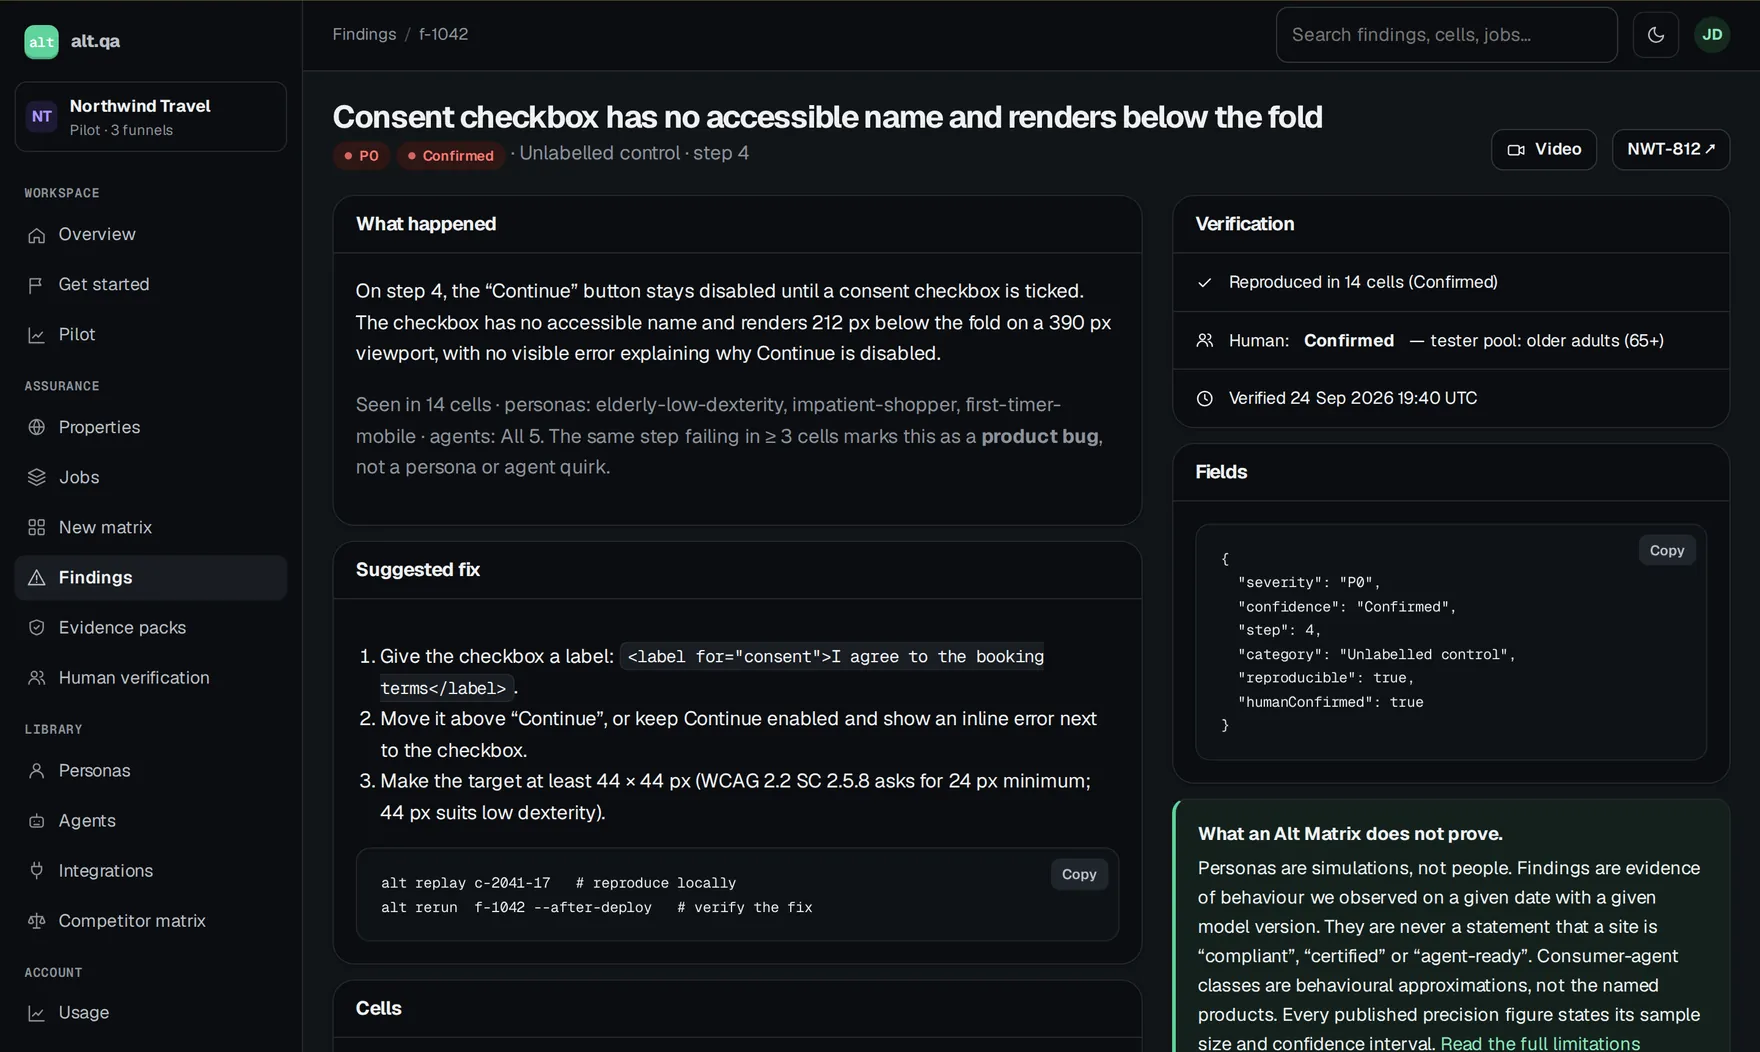
Findings written like a teammate.
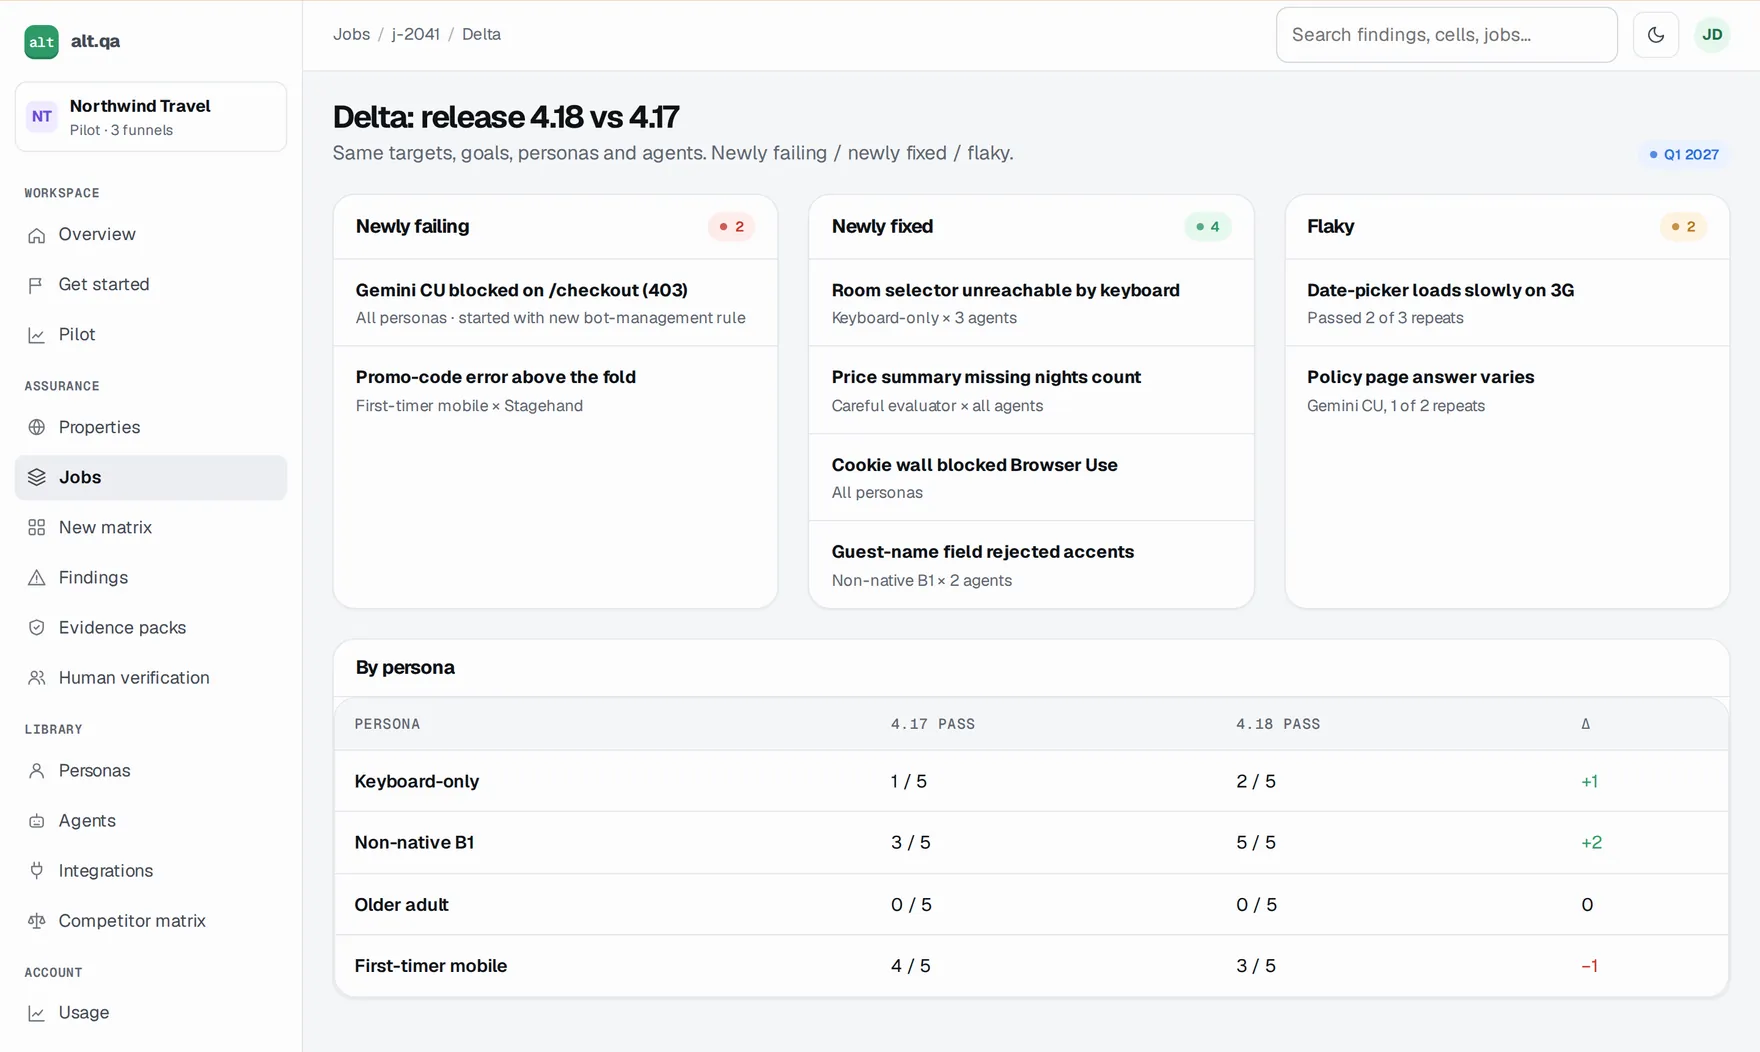
Only failures reproduced in two or more cells become tickets. Each arrives with a narrated 60-second replay, the DOM, the accessible names at the failing step, and a suggested fix.
The rules our agents follow, enforced in the engine.
Stop before payEvery run stops at payment outside a sandbox. Not configurable.
Honest identitySigned with Web Bot Auth. Never impersonates a consumer agent.
Evidence, not empathyPersonas are simulations with published precision, confirmed by paid testers.
No compliance theatreWe never say “compliant” or “certified”. See our claims policy.
Pricing
Start free. Pilot on your KPI.
Free cell$0
One persona × one agent on a funnel you own.
Self-servefrom $149/mo
Metered on cells. No seats.
Agent-Readiness Pilot$15-25K
6-8 weeks, credited on conversion.
Common questions
What does alt.qa do?
alt.qa runs real AI agents from several vendors, and behavioural personas for the people those agents act for, through your live funnels before each release, and shows the exact step where each one fails, with the recording.
How is this different from an agent-readiness score?
Scores check files like llms.txt and robots.txt. We check outcomes: did the agent actually find the product, answer the policy question, and reach payment?
Is it safe on production?
Yes, within a signed Test Authorization. Every run stops before payment, uses synthetic data, is capped at two sessions per origin and carries our signed identity.
Do you impersonate ChatGPT or other assistants?
Never. We use real vendor models under our own identity and label consumer-agent classes as behavioural approximations.
QA for the users you never meet.
Run one free cell on a funnel you own and see the step where it stalls.